


 BFSI
 HealthCare
 Edtech
 SaaS
 Automobile
 Travel
A robots.txt file is a plain text file on the root of your site that instructs web crawlers about which URLs they can request. It controls crawl traffic. The robots.txt file neither hides pages from the search results nor protects sensitive data, and the crawlers may simply choose to disregard its instructions.
The Robots Exclusion Protocol was formulated by Martijn Koster in 1994, and IETF issued it as an Internet Standards Track document in September 2022, specifying a parsing minimum of 500 KiB and advising crawlers to reuse their cached copy of the file for no longer than 24 hours as per IETF RFC 9309 (Source).
It is also known as robots.txt, robots txt, or robot txt file, and all the variants would point you to the very same file, located at yourdomain.com/robots.txt.
This robots.txt guide will explain what the file does, how its syntax works, how to create and test one, and which mistakes to avoid.
What Is Robots.txt?
A robots.txt file is placed in the top-level directory of a host, for instance https://www.example.com/robots.txt. It should be written in lowercase. The file is to be encoded in UTF-8 and have media type text/plain. Each subdomain requires its own robots.txt file.
Crawlers retrieve the robots.txt file before they retrieve any other URLs from that host. There are several blocks in a file. Instructions for Googlebot, Bingbot, and an AI crawler are different.
There are one or several user-agent lines at the beginning of a block, followed by allow or disallow rules. If a crawler does not find a specific block for its name, it will obey a block with asterisks or crawl freely.
Core Directives in a Robots.txt File
Four lines do most of the work in a robots.txt file, and each one follows the same robots.txt syntax of a field name, a colon, and a value:
- User-agent names the crawler that a group applies to, for example Googlebot, Bingbot, or an AI crawler such as GPTBot.
- Disallow blocks a path.
- Allow reopens a path inside a blocked folder, which keeps one page crawlable while its parent folder stays closed.
- Sitemap gives the full URL of your XML sitemap.
For example, Disallow: /admin/ stops compliant bots from fetching anything in the admin folder, so the login page and its assets stay out of the crawl queue. The rule matches every URL that begins with that path, including subfolders and files.
Robots.txt vs Meta Robots Tags
The table compares both methods.
| Aspect | Robots.txt | Meta Robots Tags |
|---|---|---|
| Definition | A text file at the root of your website that gives directives to crawlers | HTML tags inside a page that give instructions to crawlers |
| Location | Root directory of the host | Inside the HTML of each page |
| Control level | Host-level control over crawling of whole sections | Page-level control over indexing and link following |
| Directives | User-agent, Disallow, Allow, Sitemap | index, noindex, follow, nofollow, noarchive, nosnippet |
| Best use | Blocking crawl access to folders or URL patterns | Keeping single pages out of the index |
| Setup | Edit one text file | Add tags to the HTML of each page |
A URL blocked in robots.txt can still appear in search results as a bare link when other sites point to it. Use a noindex tag when the goal is removal. Crawlers must fetch the page to read that tag, so leave the page open to crawling.
How Does Robots.txt Work?
A crawler requests /robots.txt first, finds the group that matches its name, and fetches only the URLs that group permits. The response from your server to that request also changes what the crawler does next, which is why the status code of the file matters as much as the rules written inside it.
Robots.txt Syntax and Structure
Robots.txt syntax is simple. Each group opens with a user-agent line, and the rules beneath it apply to that crawler only. The example below shows two groups and a sitemap line.
User-agent: Googlebot
Disallow: /private/
Allow: /public/
User-agent: *
Disallow: /tmp/
Sitemap: https://www.example.com/sitemap.xml
Read the example this way:
- Googlebot may not crawl the /private/ folder or anything inside it.
- Googlebot may crawl /public/, and it ignores the asterisk group, so /tmp/ stays open to it.
- Every other crawler may not fetch /tmp/.
- The Sitemap line sits outside the groups and applies to the whole file, so any crawler can read it.
When two rules conflict, the longest matching path wins. If an allow rule and a disallow rule match with equal length, crawlers use the allow rule.
Two special characters extend robots.txt syntax. The asterisk matches any run of characters. The dollar sign marks the end of a URL, so Disallow: /*.pdf$ blocks every URL that ends in .pdf.
Add comments after a hash symbol, for example Disallow: /staging/ # block the test folder.
How the Robots Txt Allow Rule Works?
The robots txt allow rule reopens one path inside a blocked folder. Pair it with a Disallow line for the parent folder, and keep the Allow path longer than the block.
User-agent: *
Disallow: /private/
Allow: /private/press-kit.html
The longer Allow path wins here. Crawlers can fetch the press kit and nothing else in /private/.
The Crawl-delay line asks a crawler to wait a set number of seconds between requests. Google ignores it. Bing and Yandex read it.
How to Read Robots.txt?
Knowing how to read robots.txt lets you audit any site, including a competitor’s, with nothing but a browser. Follow these steps:
- Open yourdomain.com/robots.txt in a browser.
- Find the User-agent line that names your crawler, or the asterisk group when no line matches.
- Read the Disallow and Allow lines under that group, and apply the longest-match rule to each URL you care about.
- Check the Sitemap lines at the bottom of the file.
- Note its HTTP status.
Watch for a robots txt allow line that overrides a broader block above it. A 4xx response tells crawlers they may fetch anything. A 5xx response tells crawlers to assume that the server disallows the whole site, so fix server errors on this URL first.
Creating and Configuring a Robots.txt File
Use this robots.txt guide to create the file, set each rule, and confirm that Google can read it.
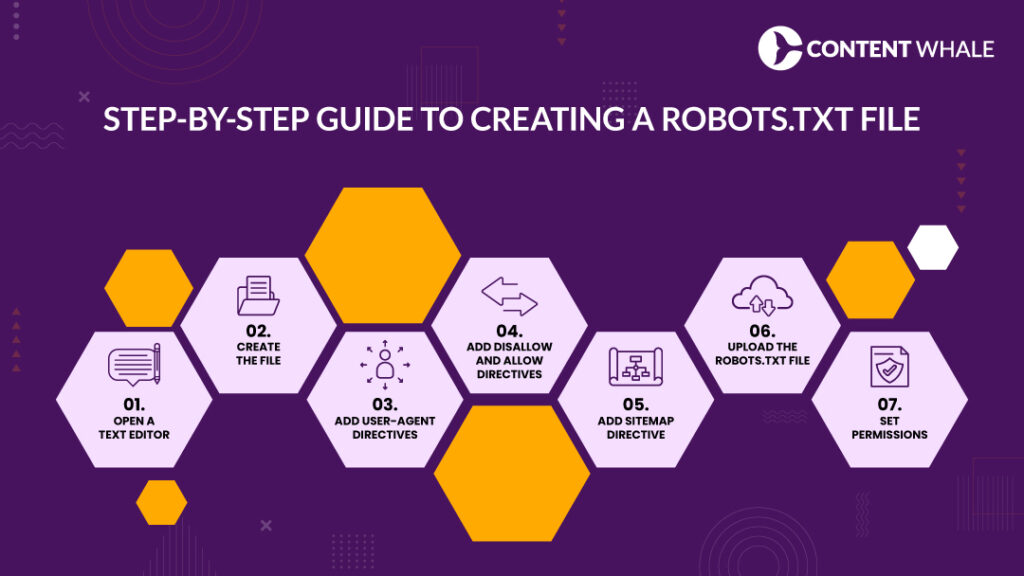
Step-by-Step Robots.txt Guide to Create the File
- Open a plain text editor such as Notepad or TextEdit, and save the file with UTF-8 encoding.
- Name the file robots.txt in lowercase.
- Add a User-agent line for each crawler you want to address, or one asterisk group for all crawlers.
- Add Disallow lines for folders that waste crawl budget.
- Add Allow lines for any exception inside a blocked folder, because the longest matching path wins.
- Add a Sitemap line.
- Upload the file to the root directory so it loads at yourdomain.com/robots.txt.
- Open the robots.txt report in Google Search Console to confirm that Google fetched the file without errors, read every rule the way you intended, and found the Sitemap line near the bottom.
Tools for Building a Robots.txt File
- CMS platforms such as WordPress, Magento, and Wix generate a basic file, and plugins like Yoast SEO and All in One SEO let you edit it.
- Online generators build the file from a form, and many owners search for a robots txt file generator first.
- The Search Console robots.txt report replaced the old robots.txt Tester in late 2023, and it shows which files Google found and any fetch errors.
- Our comparison of Google Search Console and Bing Webmaster Tools shows how each platform reports crawl problems.
Best Practices for a Robots.txt File
- Put each directive on its own line.
- Use the asterisk and the dollar sign to cover many URLs in one rule, and keep every robots txt allow exception shorter than the folder it protects.
- Match the case of your live URLs, because path matching is case-sensitive.
- Leave CSS and JavaScript files open when Google needs them to render your pages.
- Add comments.
- Retest the robots.txt file after every site migration or CMS update.
Importance of Robots.txt in SEO
The robots.txt file shapes how crawlers spend time on your site.
Crawl Budget Management
Crawl budget is the number of URLs a search engine will fetch from your site in a given period. Block low-value URLs such as internal search results, filter combinations, and session parameters so crawlers reach the pages that earn traffic.
Scale makes this matter. Content Whale’s KnowledgeHut case study grew organic visitors from 278,000 in April 2022 to over 2 million in September 2023 with 12 to 15 SEO blogs a month, and every one of those pages had to be crawlable before it could rank.
URL Parameters and Duplicate Pages
Parameter URLs such as ?sort=price or ?color=red create many addresses for one page. Disallow patterns like /*?sort= to stop crawlers spending time on them. Robots.txt does not merge ranking signals between duplicates, so add canonical tags to the pages you keep.
Server Load
Heavy sections such as faceted navigation and calendar archives can flood a server with requests. Disallow those paths. Add a Crawl-delay line for Bing and Yandex when their crawlers strain your hosting.
Sitemap Discovery
A Sitemap line gives every crawler that reads the file the location of your XML sitemap, which speeds up the discovery of new URLs. Keep the line outside any user-agent group so every crawler can read it.
Robots.txt Is Not a Security Tool
The file gives crawlers instructions. It locks nothing. Listing a path in the file makes that path public, so a Disallow line for /admin/ tells every reader where the admin folder lives. Protect private areas with a login.
Compliance also varies by crawler. A 2025 study from Duke University tracked 130 self-declared bots over 40 days and found that bots complied less often as directives grew stricter, and that AI search crawlers rarely checked the file at all, as reported in the ACM Internet Measurement Conference paper (Source).
Robots.txt for AI Crawlers
To block an AI crawler, add a group with its user-agent token. GPTBot is the token for OpenAI’s crawler.
User-agent: GPTBot
Disallow: /
Pair the rule with server-side controls when the content matters, because some crawlers ignore the file.
Common Robots.txt Mistakes and How to Avoid Them
A study that crawled 7,593 websites found 282 robots.txt files with ambiguous rules and 18 with conflicting rules, as documented in the WWW 2007 large-scale robots.txt study (Source). Knowing how to read robots.txt rules helps you spot each of these errors quickly.
In our experience working with clients on SEO audits, the first thing to rule out after a sudden traffic drop is a leftover staging rule such as Disallow: / on the live site.
Blocking Important Pages
A broad rule blocks more than intended. Disallow: /blog blocks /blog/, /blog-tips, and every other path that begins with those characters.
Use specific paths with a trailing slash, add a robots txt allow exception for any page you need open, and test the key URLs that drive traffic and leads after each change you make.
User-agent: *
Disallow: /private/
Allow: /private/public-file.html
Wrong Robots.txt Syntax and Wildcards
Misplaced wildcards and missing colons make crawlers skip a line. Crawlers try to parse each line and follow the rules they can read, so one bad line usually breaks only itself.
Validate the robots.txt syntax in the Search Console report after every edit.
Misnaming the File
A robot txt file saved as robot.txt or Robots.txt fails because crawlers request exactly /robots.txt in lowercase. The 2007 study also found misnamed files in the wild. Rename the file and upload it again.
Skipping Updates After Site Changes
A new folder structure, a migration, or a new subdomain makes old rules wrong, so review the file on every host after each change.
Blocking CSS and JavaScript Files
Google may misread pages that depend on blocked resources. Allow the folders that hold the CSS and JavaScript files your pages need to render.
Allow: /css/
Allow: /js/
Ignoring Case in Paths
Path matching is case-sensitive. /Private/ and /private/ are two different paths, so write each rule to match the live URL exactly.
Using Unsupported Directives
The protocol defines no noindex rule. Use a robots meta tag or an X-Robots-Tag header to keep a page out of the index.
<meta name=”robots” content=”noindex”>
X-Robots-Tag: noindex
Run through this list after every release that changes URLs.
Robots.txt Checklist and Next Steps
A well-built robots.txt file will direct the crawlers to your sitemap, block access to low-quality URLs, and let all the pages you wish to rank be crawled, and hence, the below tests should be done periodically. Evaluate your robots.txt file based on this robots.txt guide every quarter. Test for the following on your website:
- Confirm that your file is loading on every host at the root level and provide 200 status code.
- Ensure there is no rule blocking the pages that you wish to get indexed or the required CSS and JavaScript files.
- Confirm that the Sitemap command specifies the live XML sitemap link.
- Mark all those pages that you wish to de-index with noindex tag but ensure that they are crawlable.
- Test how to read robots.txt on your website every quarter, noting down rules that cannot be explained by anyone.
- Test your file after every migration.
Technical fixes work best next to content that matches search intent, as our guide to SEO best practices for blog writing explains.
Waaree Solar, a client of our blog writing services since May 2021, reports that its global website rank moved from 250,000 to 55,000.
Get a free SEO audit from Content Whale’s SEO services team and have an expert review your robots.txt file.
FAQs About Robots.txt
What is robots.txt file?
Robots.txt file contains information about URLs that can be crawled by search engine crawlers. It is important as it allows controlling the crawl traffic and redirects crawlers to the sitemap. This will make sure that the new pages get into the index faster and the time is spent crawling the pages that earn traffic.
How do I make robots txt files?
Launch text editor, create and name robots.txt file using UTF-8, and add User-agent, Disallow, Allow, and Sitemap lines to it. Upload the file to the root folder of the website and check it through the robots.txt report at the Search Console.
What is robots.txt syntax format?
To create valid robots.txt file syntax should begin with a User-agent line and continue with Disallow or Allow lines. Each line should contain one rule only.
How to read robots.txt rules for websites?
Visit the /robots.txt page, find the group where the crawler name is mentioned and read its Allow and Disallow lines. The longest matching path wins.
What does robots txt allow mean?
Allow line cancels the effect of Disallow line for the paths inside the folder. The Allow path should be longer than the Disallow path it overrides.
Can a robot txt file block all crawlers?
Yes. A group with User-agent: * followed by Disallow: / asks every compliant crawler to stay out of the whole site. Use it on staging sites only, because crawlers can still ignore it.
Can robots.txt disqualify a page on Google?
No. Even a blocked URL can be included in results as a plain link. Instead, add a noindex directive or make the page secure.
Is a robots txt file necessary?
No. If there is no file, crawlers can have access to all URLs.
Where can I find a robots.txt guideline document?
Google Search Central provides a robots.txt guide and a specification document, and RFC 9309 contains the technical standard for the IETF.



 Content Whale – USA


